Scalable & incrementa type discovery
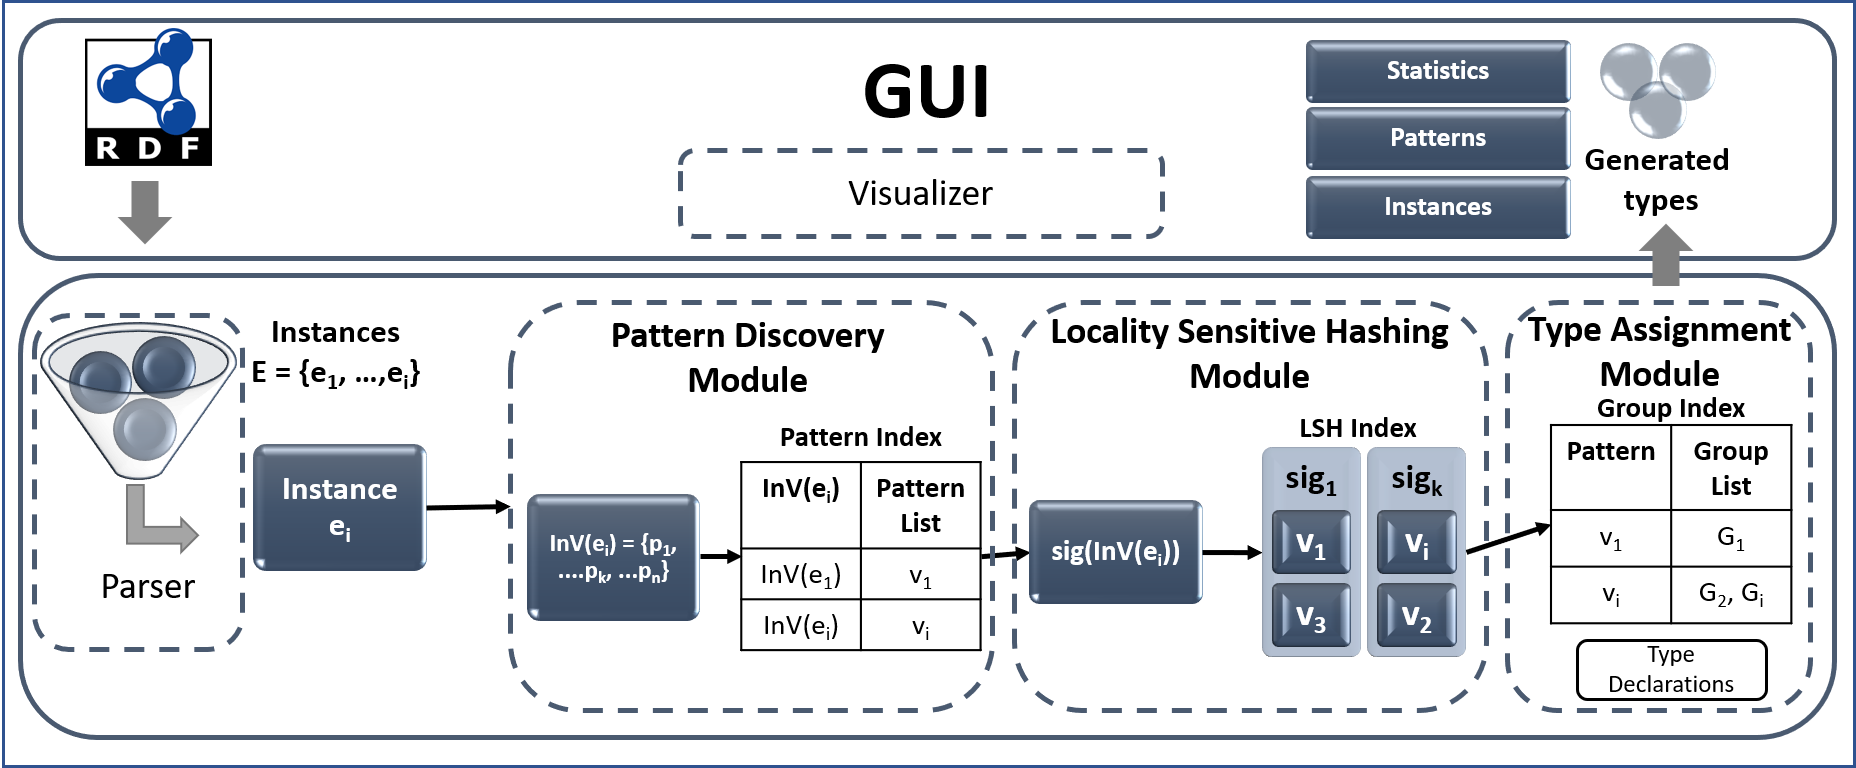
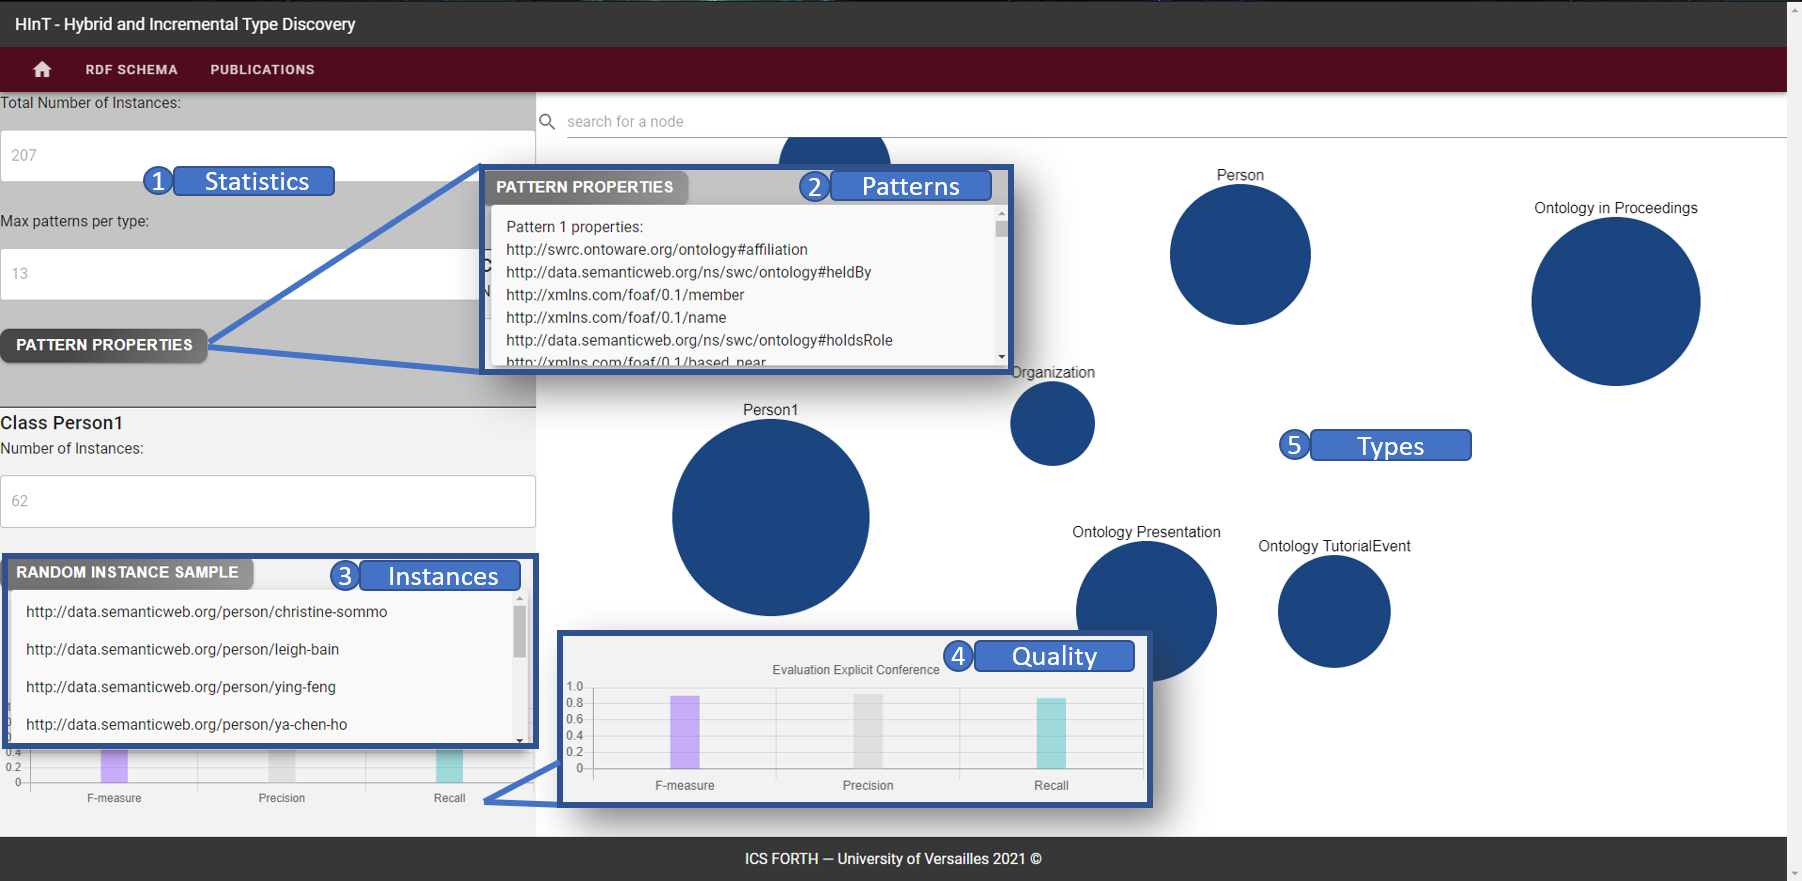
The rapid proliferation of the semantic web has led to the emergence of many weakly structured and incomplete data sources. On these sources typing information might be partially or completely missing. On the other hand, type information is essential for a number of tasks such as query answering, integration, summarization, and partitioning. Existing approaches for type discovery, either completely ignore type declarations available in the dataset (implicit type discovery approaches), or rely only on existing types, in order to complement them (explicit type enrichment approaches). In this demonstration, we present HInT, the first \textit{incremental} and \textit{hybrid} type discovery system for RDF datasets. To achieve this goal HInT identifies the patterns of the various instances, and then indexes and groups them to identify the types. Besides discovering new types, HInT exploits type information if available, to improve the quality of the discovered types by guiding the classification of the new instance in the correct group and by refining the groups already built.