Conditional Hand Image Generation using Latent Space Supervision in Random Variable Variational Autoencoders
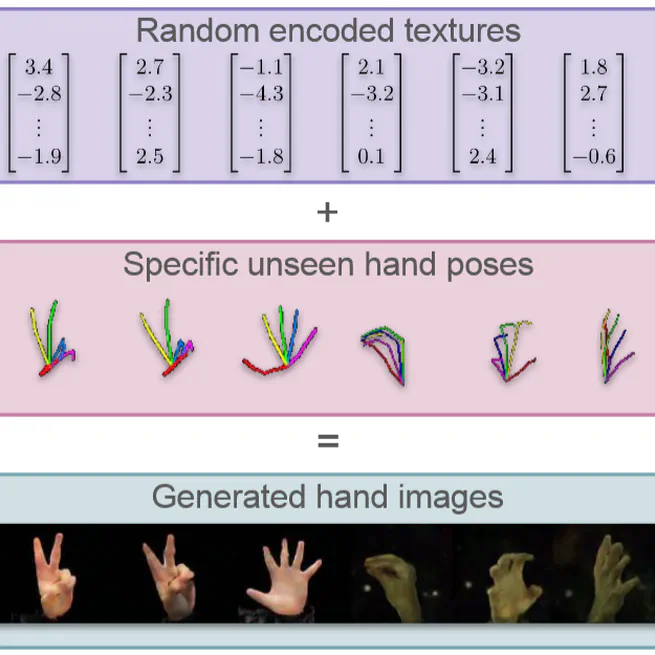
We introduce a novel framework for generating photorealistic synthetic images of human hands conditioned to a precise pose annotation. We propose a supervised Random Variable Variational Autoencoder (SRV-VAE), a model that disentangles and encodes the appearance and pose of the hand into separate components of the latent space. Appearance, representing individual subject traits, is unsupervised. Hand pose is strictly supervised and yields control over the synthesis process. Leveraging the robust RV VAE variant, our architecture ensures stable training and accurate encoding of complex hand dynamics. Our model is capable of generating hand images of previously unseen hand poses for specific subjects. Experimental results indicate the model’s efficacy in synthesizing realistic and varied hand images, holding significant promise for advancements in both academic research and practical applications such as data upsampling, where accurate hand pose and texture data is critical.
September 30, 2024
Learning to infer the depth map of a hand from its color image
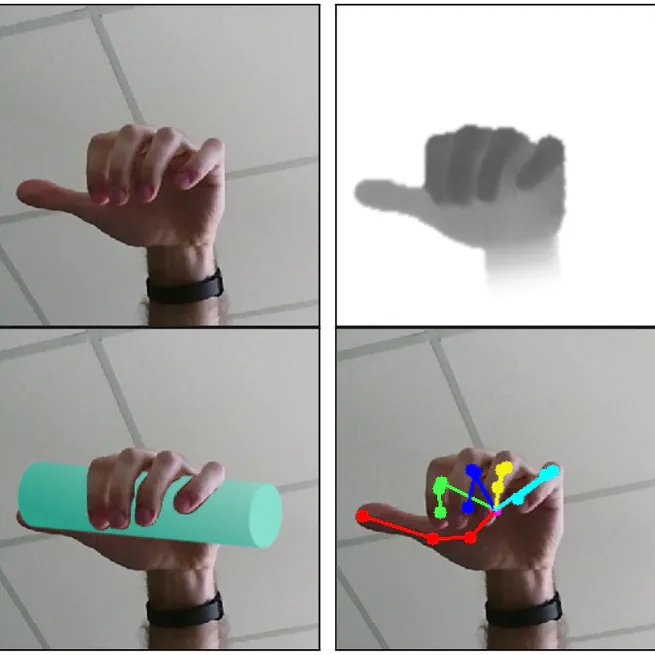
We present the first direct approach targeted explicitly on human hands that infers depth from monocular RGB images. We achieve this with a Convolutional Neural Network (CNN) that employs a stacked hourglass model as its main building block. Intermediate supervision is used in several outputs of the proposed architecture in a staged approach. To aid the process of training and inference, hand segmentation masks are also estimated in such intermediate supervision steps, and used to guide the subsequent depth estimation process. In order to train and evaluate the proposed method we compile and make publicly available HandRGBD, a new dataset of 20,601 views of hands, each consisting of an RGB image and an aligned depth map. Based on HandRGBD, we explore variants of the proposed approach in an ablative study and determine the most accurate one. The results of an extensive experimental evaluation demonstrate that hand depth estimation from a single RGB frame can be achieved with an accuracy of 22mm, which is comparable to the accuracy achieved by contemporary low-cost depth cameras. Such a 3D reconstruction of hands based on RGB information is valuable as a final result on its own right, but also as an input to several other hand analysis and perception algorithms that require depth input. In this context, the proposed approach bridges the gap between RGB and RGBD, by making all existing RGBD-based methods applicable to RGB input.
July 20, 2020
Single-shot 3D hand pose estimation using radial basis function networks trained on synthetic data
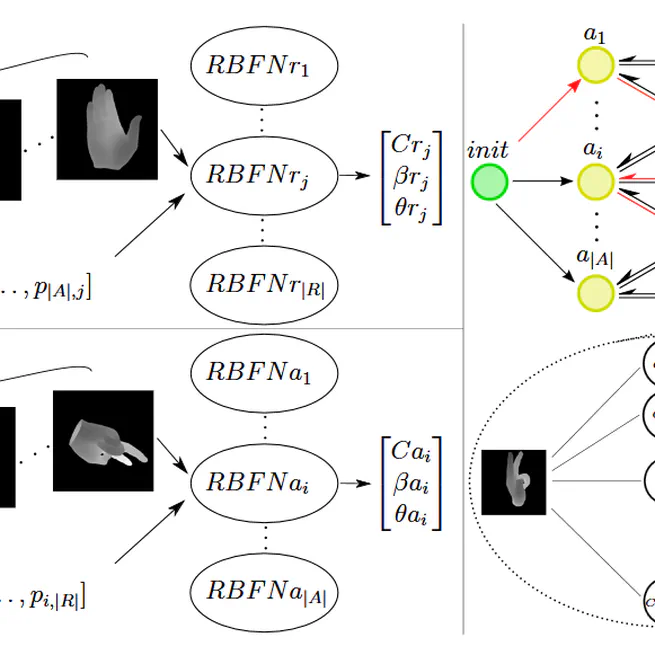
In this work, we present a novel framework to perform single-shot hand pose estimation using depth data as input. The method follows a coarse to fine strategy and employs several radial basis function networks (RBFNs) that are trained on a dataset containing only synthetically generated depth maps. Thus, compared to most contemporary deep learning approaches, it does not require the laborious annotation of large, real-world datasets. At run time, an initialization RBFN is used to provide a rough estimation of the hand’s 3D pose. Subsequently, several specialized RBFNs are employed to improve that initial estimation in an iterative refinement scheme. To train the RBFNs, we select a set of hand poses from a real-world sequence that are as diverse as possible. We use this representative set, along with a dense sampling of all possible rotations, as a seed to generate a large synthetic training set. The method is parallelizable, taking advantage of the inherent data parallelism of RBFNs. Furthermore, the method requires few real-world data and virtually no manual annotation. We perform a quantitative evaluation of our method on a testing sequence of our own. We also present quantitative and qualitative results on a public dataset that is commonly used to evaluate hand pose estimation and tracking methods. We show that in all cases, our approach achieves promising results. Moreover, it can achieve comparable or even faster computational performance than current deep learning approaches but on a single CPU core, i.e., without requiring GPU processing.
February 27, 2019